

Continuous LLM evaluation for reliable enterprise customer support AI
Client: Global Fortune 50 enterprise technology manufacturer | Solution: Continuous LLM evaluation helped improve AI response reliability, validate model and prompt changes, and bring greater confidence to AI releases.
Challenge - Building trust in enterprise support AI
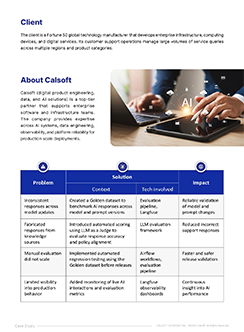
The client’s AI support agent handled product and service queries using LLMs and internal knowledge sources. But model and prompt updates produced inconsistent responses, manual reviews could not scale, and limited production visibility made it difficult to identify quality issues or confidently evaluate model upgrades.
Solution - Establishing Continuous LLM Evaluation for Reliable AI
- Created a Golden dataset to benchmark responses across model and prompt versions
- Automated evaluation and regression testing before releases
- Used LLM-as-a-Judge to assess correctness, relevance, and policy alignment
- Added production monitoring to detect drift, hallucinations, and response changes
The solution enabled continuous evaluation across development and production, helping the client improve response reliability, validate releases more safely, and make model decisions using measurable benchmarks.
Business Value


To Know More
About how we can align our expertise to your requirements, reach out to us.