At 2:40 a.m., a customer in Frankfurt logs a severity-2 ticket. L1 can’t reproduce the fault and escalates it. L2 asks the customer for logs the customer already sent. By 9 a.m. in San Jose, a senior engineer has been pulled off a release to read a thread of fourteen messages. None of them contain the log file. Every tier did its job. The ticket still lost a day.
Most product companies have support tiers. Far fewer have boundaries between them. A tier is a group of people. A boundary is the agreement that decides what crosses from one group to the next, what travels with it, and who owns the clock while it moves. Skip the boundary and each tier turns into a waiting room.
The damage lands in the most expensive place. L1 agents sit on technical issues they can’t close. L2 and L3 engineers lose hours to escalations that never needed them, while backlogs grow quietly until an SLA breach surfaces in a renewal call. Structured multi-tier support exists to break that pattern, and it starts by treating handoffs as engineering work rather than admin.
Why more headcount makes it worse
Hiring feels like progress. More L1 agents means more tickets touched in the first hour. It does not mean more tickets solved, because new agents escalate whatever they don’t recognize, and the queue simply moves upstairs to the people whose time costs the most. Each escalation also restarts the clock with someone who has to relearn the problem from scratch. Escalation volume grows with the team.
The next fix is usually a chatbot at the front door. Customers notice. According to Gartner, 2026, 87% of customers say companies using GenAI for service must offer a way to reach a human agent. The same survey of 3,566 B2B and B2C customers found something more useful: in B2B, 74% of GenAI users have already used it to complete a task on their behalf. Customers will let AI do the work. They won’t let it stand in the way.
“Service leaders should not use GenAI as a mandatory first step for every issue,” Eric Keller, Sr Director Analyst, Gartner
So put AI where it gathers context and closes known issues. Then make it hand over cleanly. That handover is a boundary too, and it fails for the same reasons the human ones do.
What a working handoff looks like
Calsoft starts with the tickets, not the org chart. The first step is a review of ticket logs, SLA data and escalation patterns, because the real tier boundaries are already visible in where tickets stall.
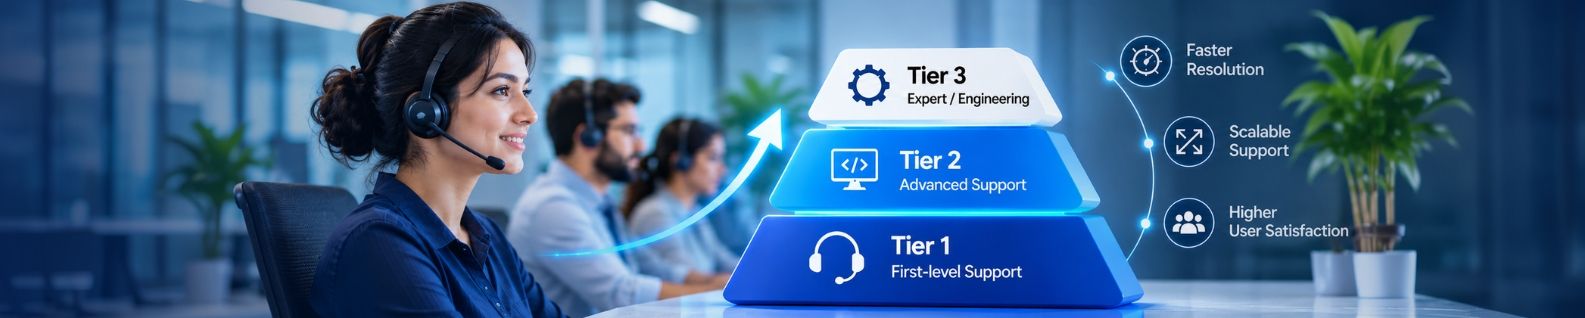
From that review, every tier gets a written scope. L1 runs 24x7 intake, resolves known issues and keeps the knowledge base current. L2 handles log analysis, API troubleshooting and environment-specific validation. L3 owns source-code triage, hotfix coordination, release-impact analysis and RCA, the root cause analysis that explains why a fault happened so it doesn’t happen twice.
The boundaries get the same rigor. Ownership maps decide who holds each issue type. Auto-routing triggers move a ticket without someone deciding by hand. SLA dashboards show where the clock is running. Every escalation travels with a packet: logs, environment details, steps already tried and a working hypothesis. A ticket without one goes back, not up. All of it sits inside the tools teams already use, from Jira and ServiceNow to Freshdesk, PagerDuty and GitHub.
The return path matters most. If L3 fixes something L1 could have handled, the fix travels back down as a knowledge base article. According to Gartner, 2026, 58% of service leaders plan to upskill agents into knowledge management specialists. The logic is plain. Knowledge that lives only in an engineer’s head doesn’t scale. It leaves when they do.
Calsoft pilots L1 and L2 first, measures the outcome, then adds L3. The pilot exists to prove the boundaries hold before anyone touches production code. Teams can hand over all three tiers or co-manage them alongside their own engineers.
A global IT infrastructure services company had enterprise support spread across four operating systems and a few veteran experts holding it together. See how Calsoft restructured its L1 to L3 operations around automated validation and unified SLA tracking. Download the case study
Should you swarm instead?
Some support leaders would scrap tiers entirely. The Consortium for Service Innovation’s Intelligent Swarming model routes each new case straight to the people best placed to solve it, with no escalation ladder at all. For novel, severe problems, that instinct is right. Pull the experts in early and let them work together.
Known, repeatable issues are different. A documented fix applied in ten minutes beats a group call every time. Most mature support teams end up running both, swarming the unfamiliar and tiering the familiar, which only works if the boundaries between them are written down. The mistake is choosing one model for every ticket and defending it in budget meetings.
The engineer reading fourteen messages at 9 a.m. doesn’t need more colleagues. She needs the log file to arrive with the ticket.
FAQs
What is the difference between L1, L2 and L3 support?
L1 handles intake and known issues using the knowledge base. L2 investigates deeper problems through logs, APIs and environment checks. L3 works at code level: triage, hotfixes and root cause analysis. Each tier should close what it can and hand over only with full context.
When should a software company formalize tiered support?
Watch for four signals. Ticket volume is spreading across time zones. Your product runs in configurable or multi-tenant deployments. Engineers keep fixing the same basic issues. Nobody can show clearly who owns the backlog or whether SLAs are being met.
Can tiered support be co-managed with an in-house team?
Yes. Many companies keep L3 close to their own engineers and hand L1 and L2 to a partner, or share every tier. What matters is a single ownership map, shared tools and one SLA view, so the customer never sees the seam.